Converse-Diarization
Evaluates frontier AI and speaker diarization models on Real World Conversational Data, measuring diarization error rate (DER): missed, false, and mis-attributed speech.
Research & Evals
We believe voice will be the natural interface between people and AI, but human speech is uniquely hard to get right. Unlike code or math, there is rarely one right answer: a good conversation depends on the setting, and every utterance carries emotion, tone, pace, accent, and language on top of its words. Converse tests whether voice-native frontier models can understand, speak, and act on real-world speech the way people do.
Evaluates frontier AI and speaker diarization models on Real World Conversational Data, measuring diarization error rate (DER): missed, false, and mis-attributed speech.
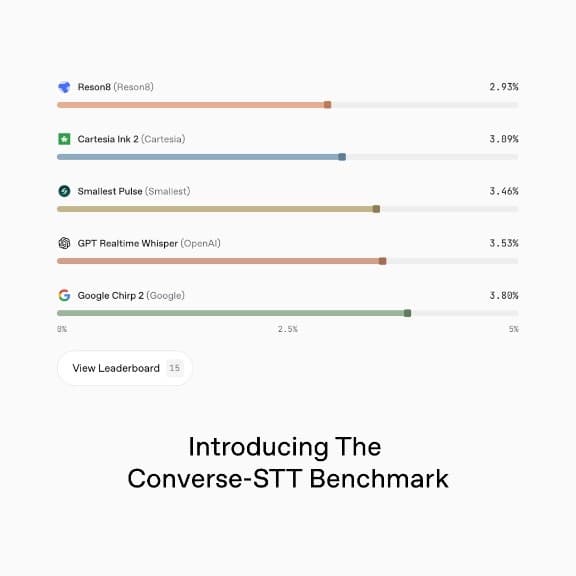
Evaluates frontier AI and speech-to-text models on Real World Conversational Data and on agent-generated Pipecat audio, measuring word error rate (WER) on each.
The Problem
AIcansolveolympiadproblems.Itstilllackshumannuance.
We'reinaTechnologicalRenaissance.Modelshavememorizedtheinternet.Theycanwriteessays,passbarexams,andprovetheorems.Butaskonetonegotiateadeal,comfortagrievingpatient,orspeakwiththewarmthandtimingofarealhumanvoice—andtheillusionbreaks.
Humanexpertiseisstaggeringlycomplex.Itspanseverymodalityandeveryculture—howasurgeonseestheoneshadowonascanthatchangeseverything,howatraderhearsriskinapausebetweenwords,howatherapistreadsafacebeforeasinglesentenceisspoken,howmeaningshiftsbetweenlanguages,accents,anddialectsthatnomodelwastrainedtounderstand.
Noneofthiswaseverinthetrainingdata.Scalingcomputewon'tconjureit.Syntheticdatawon'tapproximateit.Thebottleneckwasneverintelligence—it'stherichnessoflivedhumanexperience.

Our Solution
Weencodehumanexpertiseintomodelsthatworkfortherealworld.
We'reanappliedresearchlabbuildingthedatainfrastructureandhumanexpertisenetworktoencodereal-worldknowledgeintofrontiermodels—acrosseverymodality,language,anddomain.
Wepartnerwitheliteprofessionalstocapturewhattheyactuallydo.Thereasoningbehindadiagnosis.Theinstinctinanegotiation.Thecadenceofanativespeaker.Theengineeringinsightinadesigndecision.Themicro-expressionsamachinehasneverbeentaughttosee.
ThisflowsthroughourDataFoundry—apurpose-builtenginethattransformsrawexpertiseintostructuredtrainingdata,alignmentsignals,andrigorousevaluationsatscale.FromPhDmathematiciansandvoiceactorstoconstitutionallawyersandlinguists,everydiscipline,accent,anddialectgetsitsownpipeline.
Conversational AI
Closing the gaps our benchmarks expose takes data recorded the way people actually talk: full-duplex captures, emotional tagging, prosodic markers, scenario-anchored conversations, human preference data, and the evaluation loops that turn raw audio into training signal. This is the catalogue we ship to the labs building the next generation of conversational AI.
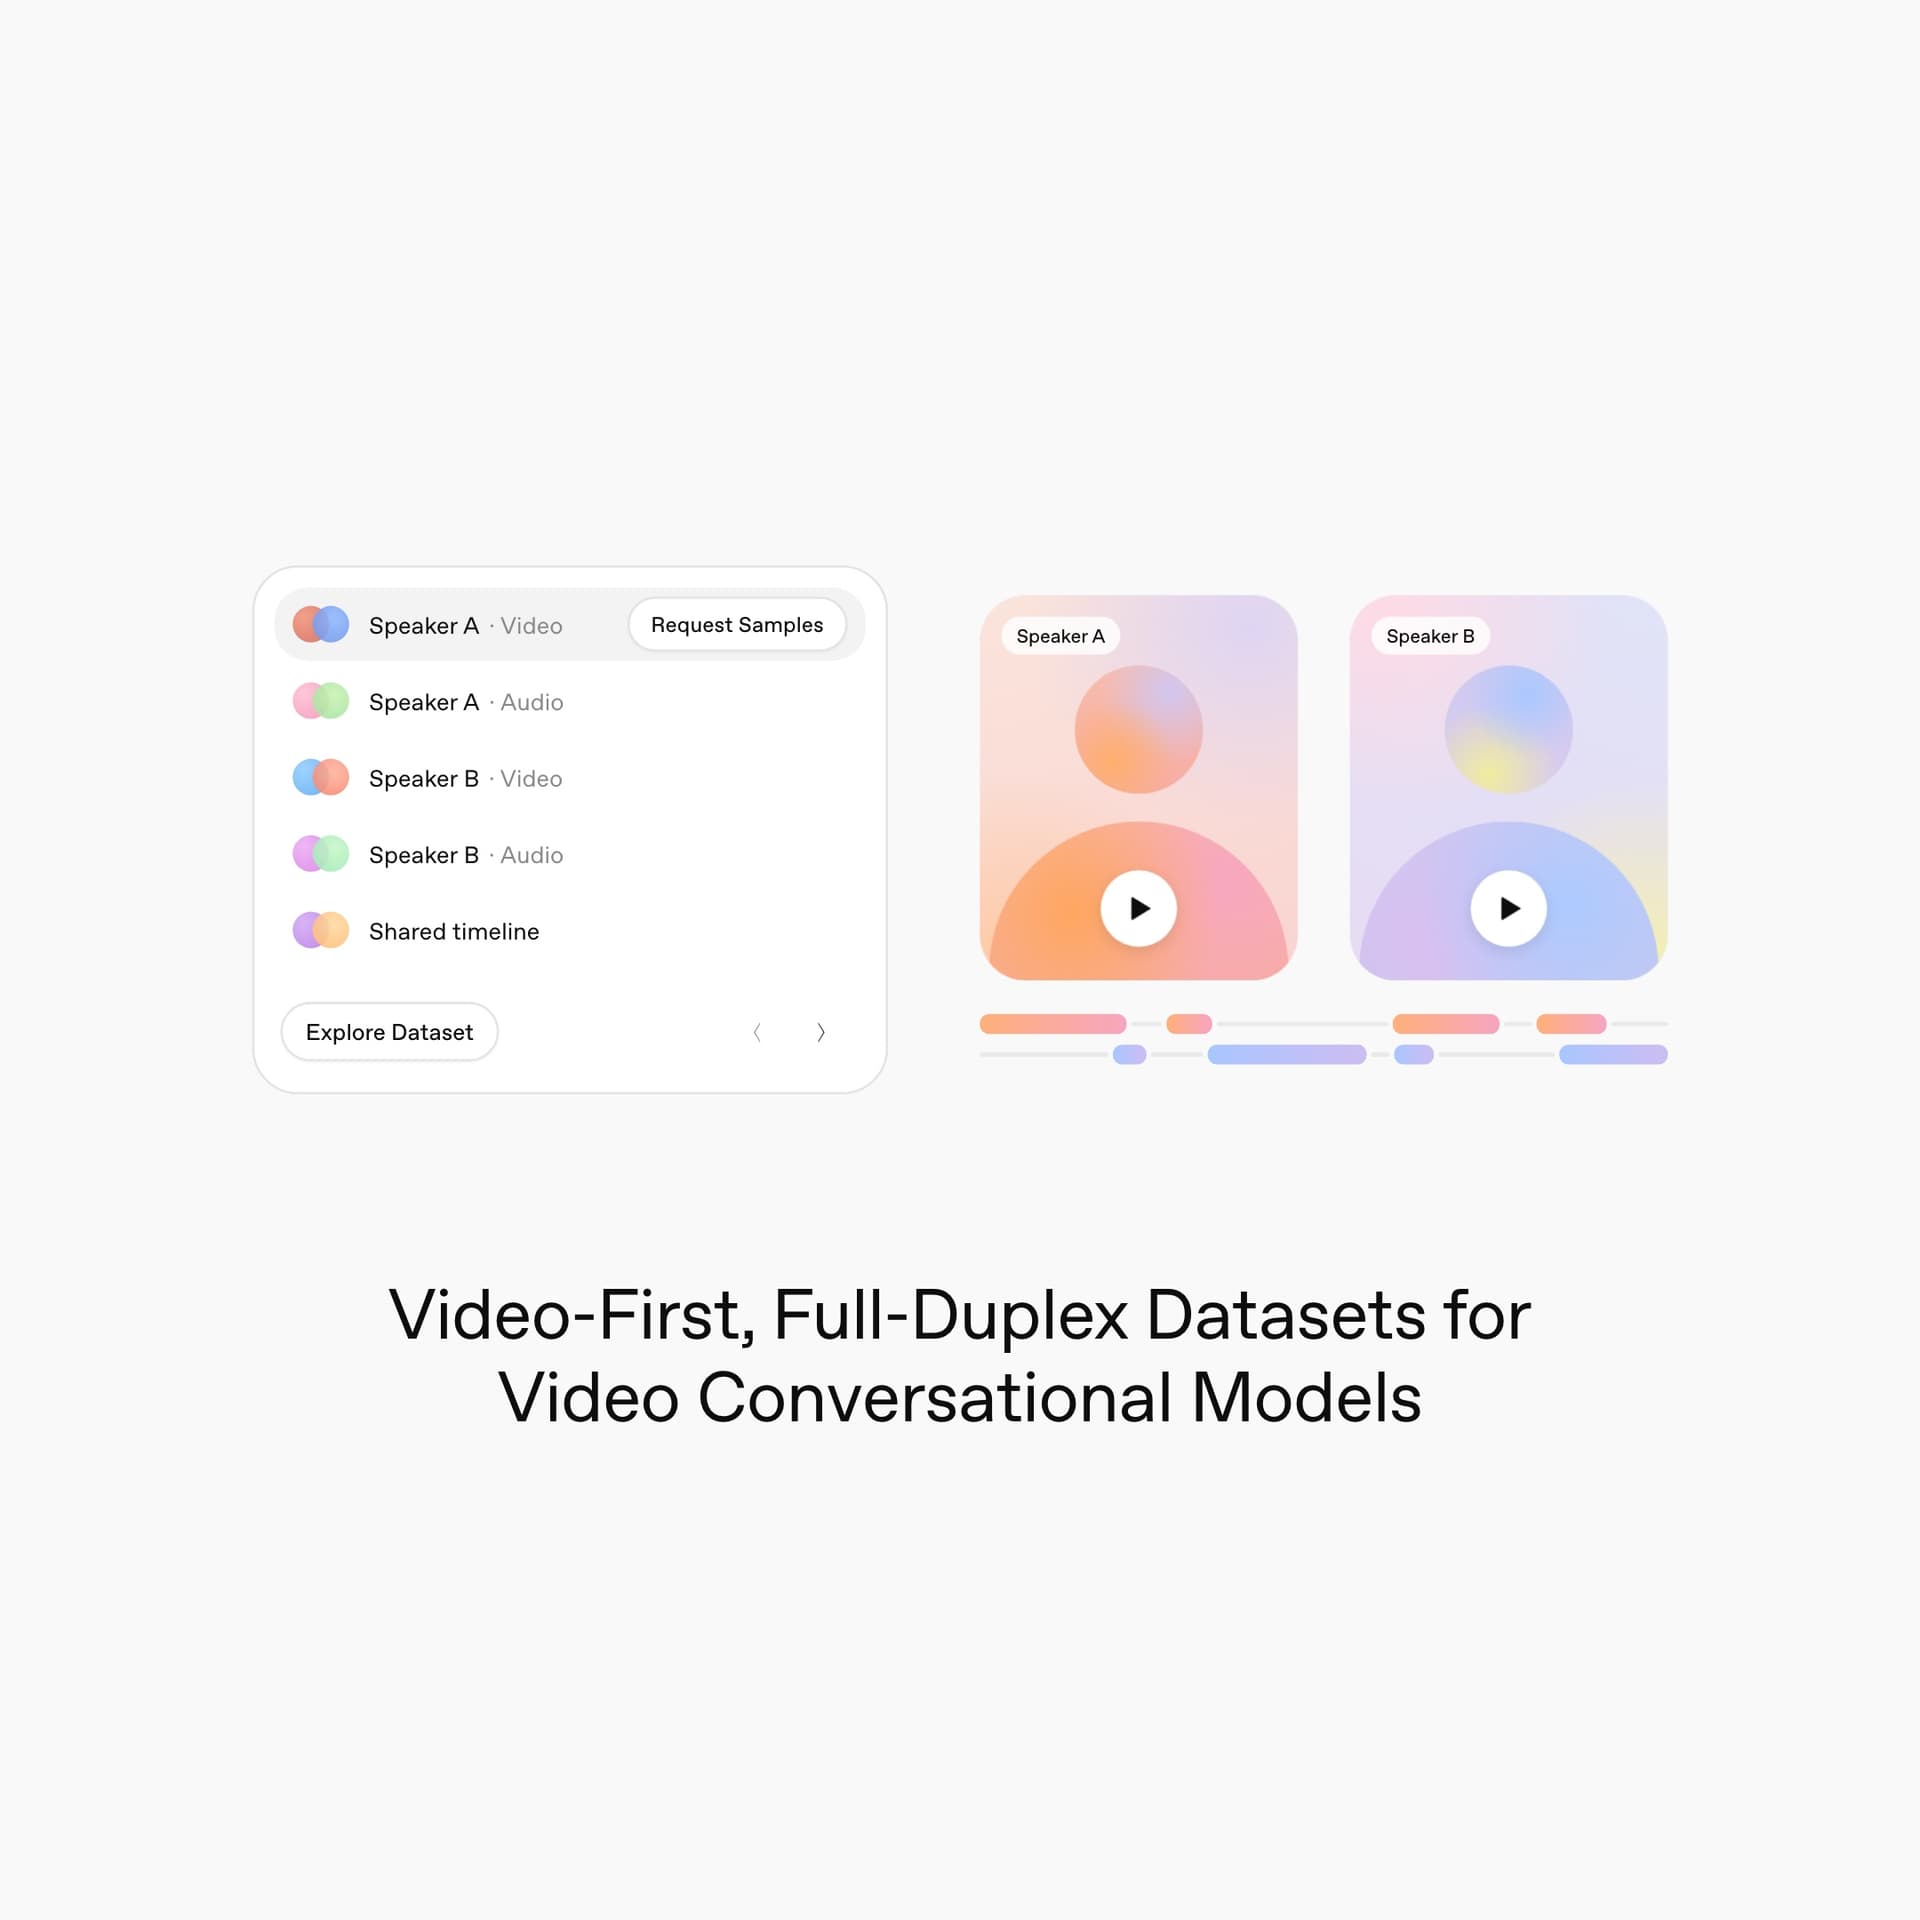
Two-speaker conversations captured at 48 kHz with isolated channels, overlap, backchannels, and barge-in preserved verbatim — the training audio behind real-time, conversational voice agents.
Task-anchored sessions across medical intake, customer support, technical interviews, and emergency calls — tagged by scenario, role, and intent for vertical voice agents.
The odor of spring makes young hearts jump.
Single-speaker performance reads from voice actors and trained narrators, phonetically balanced with controlled emotion ranges and multiple takes per line — production-grade material for TTS, voice cloning, and speech-to-speech.
Because there's a lot of implications there. You know, you can't do that. <breath/>
05:03.2BRight.
05:06.3AAnd you can't do a rigorous... well, I can't <breath/> do a rigorous workout, like, in the evening and then go to bed, you know?
05:09.6BRight.
Word-level transcripts, diarization, prosodic markers, scenario and role labels, continuous emotional tagging, and human preference scores — the training signal that turns raw audio into controllable, evaluable speech.
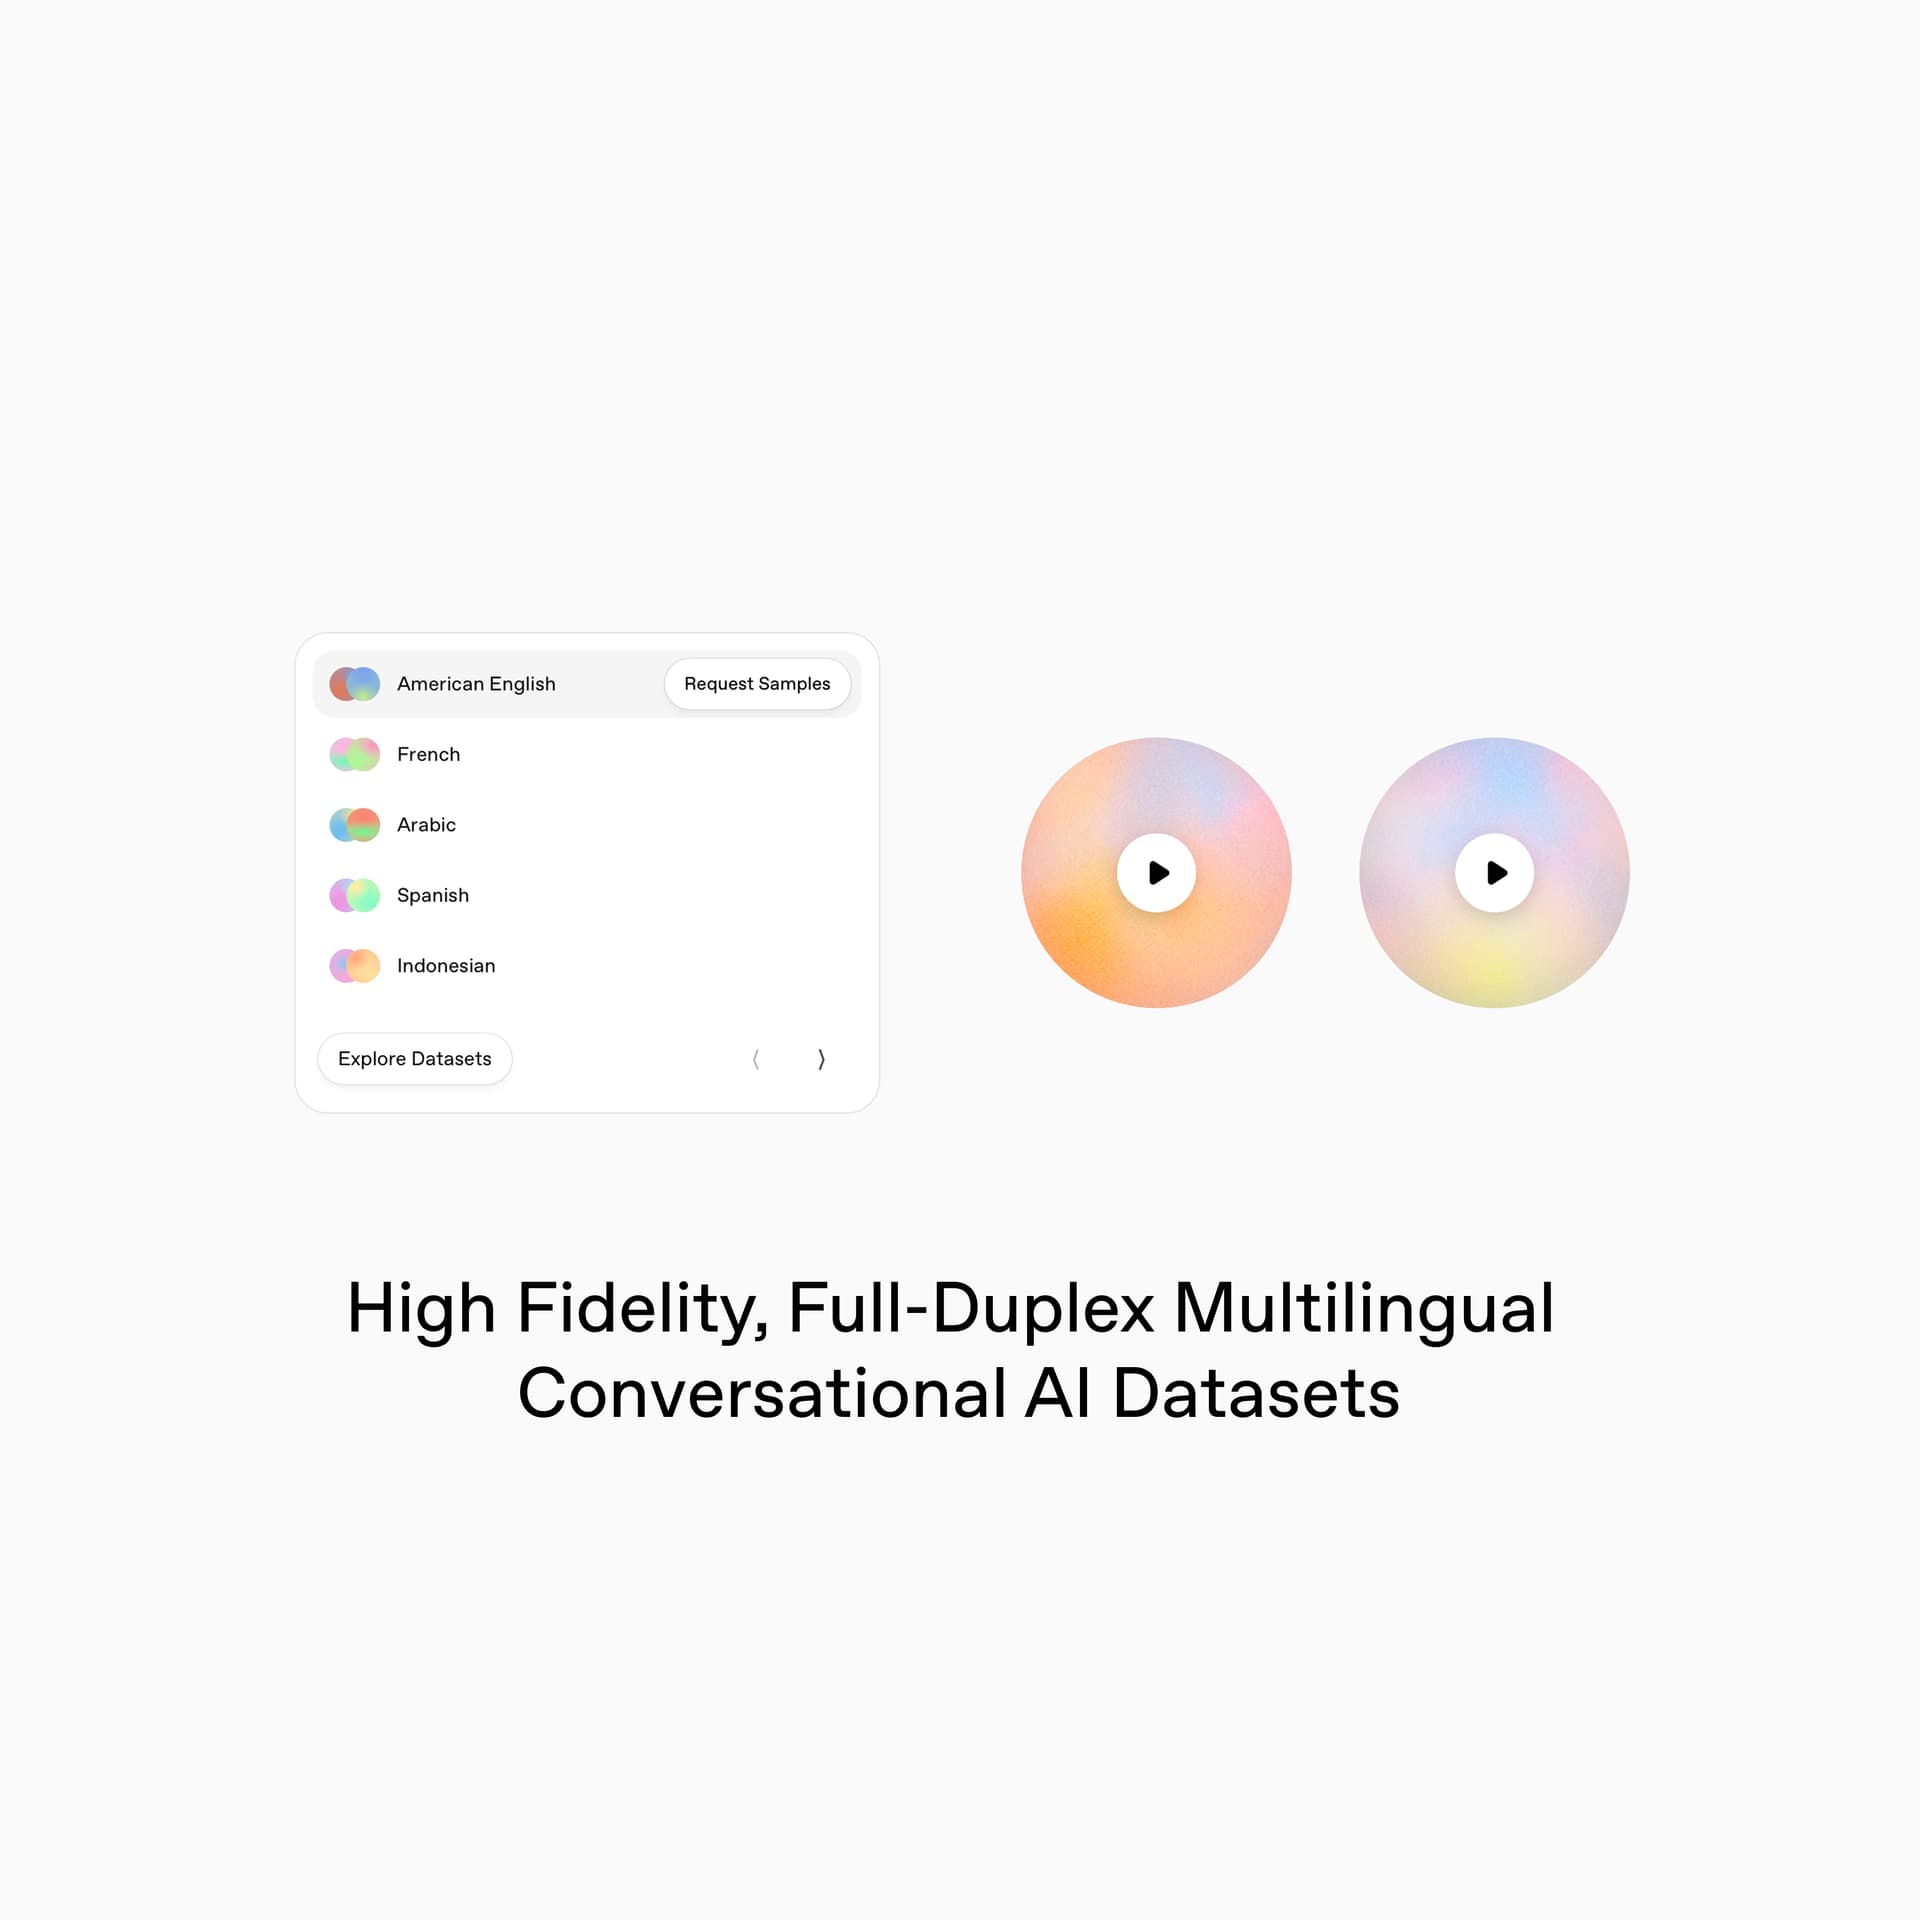
Available in 40+ languages
 American English
 English
 Spanish
 French
 German
 Italian
 Portuguese
 Dutch
 Polish
 Russian
 Ukrainian
 Czech
 Slovak
 Hungarian
 Romanian
 Bulgarian
 Serbian
 Croatian
 Greek
 Swedish
 Norwegian
 Danish
 Finnish
 Icelandic
 Irish
 Turkish
 Hebrew
 Arabic
 Persian
 Urdu
 Hindi
 Bengali
 Mandarin
 Japanese
 Korean
 Vietnamese
 Thai
 Indonesian
 Malay
 FilipinoAmerican EnglishEnglishSpanishFrenchGermanItalianPortugueseDutchPolishRussianUkrainianCzechSlovakHungarianRomanianBulgarianSerbianCroatianGreekSwedishNorwegianDanishFinnishIcelandicIrishTurkishHebrewArabicPersianUrduHindiBengaliMandarinJapaneseKoreanVietnameseThaiIndonesianMalayFilipino
Benchmarks & Leaderboards
Metric
Model
Score
 Pyannote Community-1 (pyannote)
 DiariZen WavLM Large s80 MD v2 (BUT)
 Nemotron 3 Diarization (NVIDIA)
 Scribe v2 (ElevenLabs)
 Voxtral Mini Transcribe 2 (Mistral)
 Grok Voice Transcribe 2.0 (xAI)
 GPT-4o Transcribe Diarize (OpenAI)
 MAI Transcribe 2 (direct) (Microsoft)
 Gemini 3.5 Transcribe (Google)
Grok STT 1.0 (xAI)
 Muse Voice Transcribe 1.0 (Meta)